Resource library

Evaluating Coding Agent Capabilities with Terminal-Bench: Snorkel’s Role in Building the Next Generation Benchmark

Closing the Evaluation Gap in Agentic AI
Announcing a $3M commitment to launch Open Benchmarks Grants

Benchtalks #1: Alex Shaw (Terminal-Bench, Harbor) – Building the Benchmark Factory
Building FinQA: An Open RL Environment for Financial Reasoning Agents


Grok 4.7 was evaluated on Senior SWE-Bench, our benchmark for measuring whether coding agents work like senior engineers. It reaches a tasteful pass@3 of 40.0%, up from 38.9% for Grok 4.6, ranking sixth overall at $0.24 per trial, which is a fraction of the cost compared to Opus 4.8. Benchmark Senior SWE-Bench evaluates agents as compared to a senior engineer….
Today, I’m excited to announce Snorkel’s $350M Series E financing at a $3.5B valuation, led by Insight and S32, with participation from Third Point, March, Blumberg, Allegis, Standard VC, Frontline, and existing investors Addition, Lightspeed, Greylock, GV, P7, Wells Fargo, Walden Catalyst Ventures, and Factory.
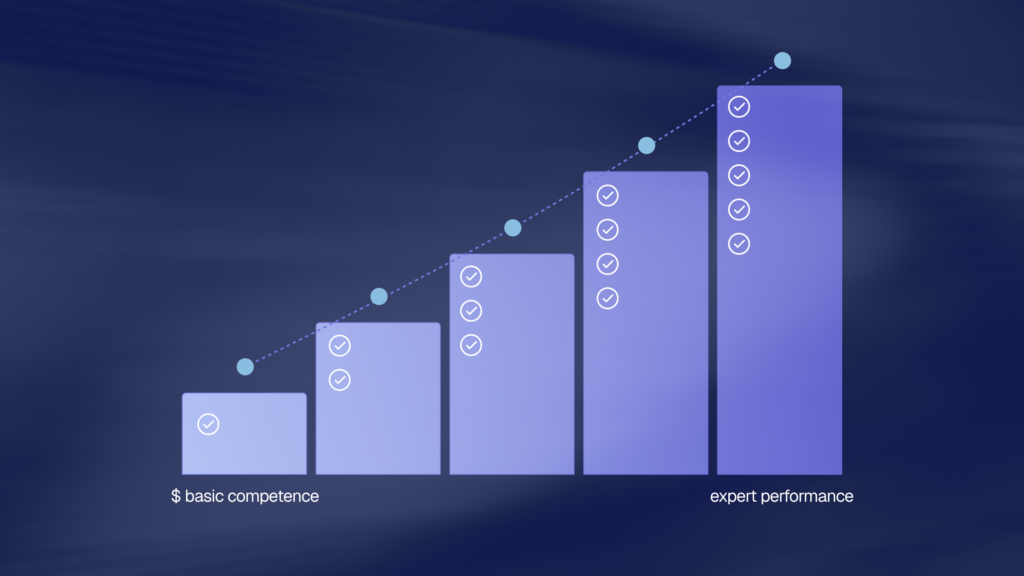
A student does not go from 1st to 12th grade in a single step. Each grade builds on a specific set of skills, and each one assumes the previous skills have already been mastered. Nobody learns calculus without algebra. When a student skips ahead anyway, what they end up with is memorization rather than understanding. The gaps show up later,…
The speed of new frontier model releases keeps accelerating. Meanwhile benchmarks struggle to keep up and saturate quickly, often being left in the dust. Most benchmarks are static datasets with no active maintenance, causing them to lose value fast. Some benchmarks are looking to change this by becoming Continuous Benchmarks. Terminal-Bench is one of the most widely reported benchmarks on…
Terminal-Bench 3.0 (formerly Frontier-Bench) recently launched, built to track what AI agents can and can’t do across real computer work. Terminal-Bench 2.1 has been saturating, with top agents reaching 84%; on Terminal-Bench 3.0, the best model, Claude Opus 5, achieves just 43.5%. Terminal-Bench 3.0 raises the bar with 74 authentic, verifiable tasks across 7 domains, designed to expose meaningful gaps…
Anthropic’s Claude Opus 5 recently debuted as the second model overall on the current Senior SWE-bench leaderboard, behind Fable 5. It also achieves the highest score of any evaluated model on the benchmark’s Bug & Performance Investigation category, reinforcing the rapid progress frontier coding models continue to make on increasingly realistic software engineering tasks. Just as notable, Opus 5 reaches…
Frontier-Bench launched this week – the successor to Terminal-Bench, built to track what AI agents can and can’t do across real computer work. Terminal-Bench 2.1 has been saturating, with top agents clearing 75-84%; on Frontier-Bench’s launch set of 74 tasks across 7 domains, the best mode Opus 5 achieving 43.3%. Snorkel AI contributed as a task author and data partner,…
Most agent benchmarks still evaluate a thin slice of the job. The agent receives a task, produces an answer, gets scored, and the episode ends. Enterprise workflows work differently. An underwriting agent may need to read policy documents, inspect customer records, call internal tools, ask a simulated user for missing information, update state, and follow approval rules. A correct final…
Long-horizon agents operate across many dependent states and transitions, often spanning multiple tools, environments, and periods of external feedback. The difficulty comes from preserving coherent progress as earlier decisions constrain later actions. A single workflow may involve researching evidence, changing files or records, waiting for external responses, revising plans, validating intermediate results, and returning to earlier systems with new information….