Category

Research

Snorkel AI emerged from a research project, and we remain closely connected to the research community. Students and professors associated with the Snorkel project continue to publish academic papers that push the field forward, and the Snorkel AI research team integrates the most promising of those ideas into our platform.

Our picks

Image for Getting better performance from foundation models (with less data)
Getting better performance from foundation models (with less data)
August 4, 2023
•
Fred Sala
Image for Snorkel AI researchers present 18 papers at NeurIPS 2023
Snorkel AI researchers present 18 papers at NeurIPS 2023
The Snorkel AI team will present 18 research papers and talks at the 2023 Neural Information Processing Systems (NeurIPS) conference from December 10-16. The Snorkel papers cover a broad range of topics including fairness, semi-supervised learning, large language models (LLMs), and domain-specific models. Snorkel AI is proud of its roots in the research community and endeavors to remain at the forefront
October 31, 2023
•
Team Snorkel
Image for Long context models in the enterprise: benchmarks and beyond
Long context models in the enterprise: benchmarks and beyond
Snorkel researchers devised a new way to evaluate long context models and address their “lost-in-the-middle” challenges with mediod voting.
June 6, 2024
•
Amanda Dsouza

All articles on Research

the-fututre-of-coding-benchmarks
Benchtalks #2: The Future of Coding Benchmarks with John Yang (SWE-Bench, ProgramBench)
For our second Benchtalks, the series dedicated to the researchers building the measurement toolkits that frontier labs hill-climb on, Snorkel AI co-founder Vincent Sunn Chen sat down with John Yang, a Stanford PhD student and creator of the SWE-bench franchise, SWE-smith, CodeClash, and most recently ProgramBench. Highlights More on ProgramBench: See the benchmark and the upcoming leaderboard at programbench.com. More from John Yang: Publications and writing at john-b-yang.github.io. Snorkel
May 21, 2026
•
Vincent Sunn Chen
Image
Why Coding Agents Need Better Data, Evals, and Environments
Coding agents have moved from tab-complete to teammate. They autonomously inspect repositories, edit files, run commands, diagnose failures, and work through multi-step engineering tasks. That creates a harder reliability problem. A model that only suggests code is easy for a human to evaluate. A coding agent refactoring your repository and testing its own changes is much harder to supervise –
May 6, 2026
•
Justin Bauer
Image
Benchmarks should shape the frontier, not just measure it
Since launching the Open Benchmarks Grants, we’ve received more than 100 applications from academic groups and industry labs spanning a wide range of domains and capabilities. As the best benchmarks have driven how the field allocates research effort, the bar for what counts as useful has risen. Here, we share what’s now table stakes for useful benchmarks, and what separates
April 6, 2026
•
Vincent Sunn Chen
Image
Benchtalks #1: Alex Shaw (Terminal-Bench, Harbor) – Building the Benchmark Factory
To kick off our inaugural Benchtalks, a series dedicated to the researchers building these measurement toolkits, Snorkel AI co-founder Vincent Sunn Chen sat down with Alex Shaw, Founding MTS at Laude Institute and co-creator of Terminal-Bench and Harbor. Highlights More on Terminal-Bench: See the leaderboard and the catalog of tasks at tbench.ai. Explore Harbor: Learn how to scale your agent
March 31, 2026
•
Vincent Sunn Chen
Image
Building FinQA: An Open RL Environment for Financial Reasoning Agents
TL;DR: We built FinQA — a financial question-answering environment with 290 expert-curated questions across 22 public companies, now available on OpenEnv. Agents use MCP tools to discover schemas, write constrained SQL queries, and answer multi-step questions from real SEC 10-K filings. Most open-source models struggle with this kind of multi-step tool use, and even frontier closed-source models, while more accurate,
March 30, 2026
•
Bhavishya Pohani
Image
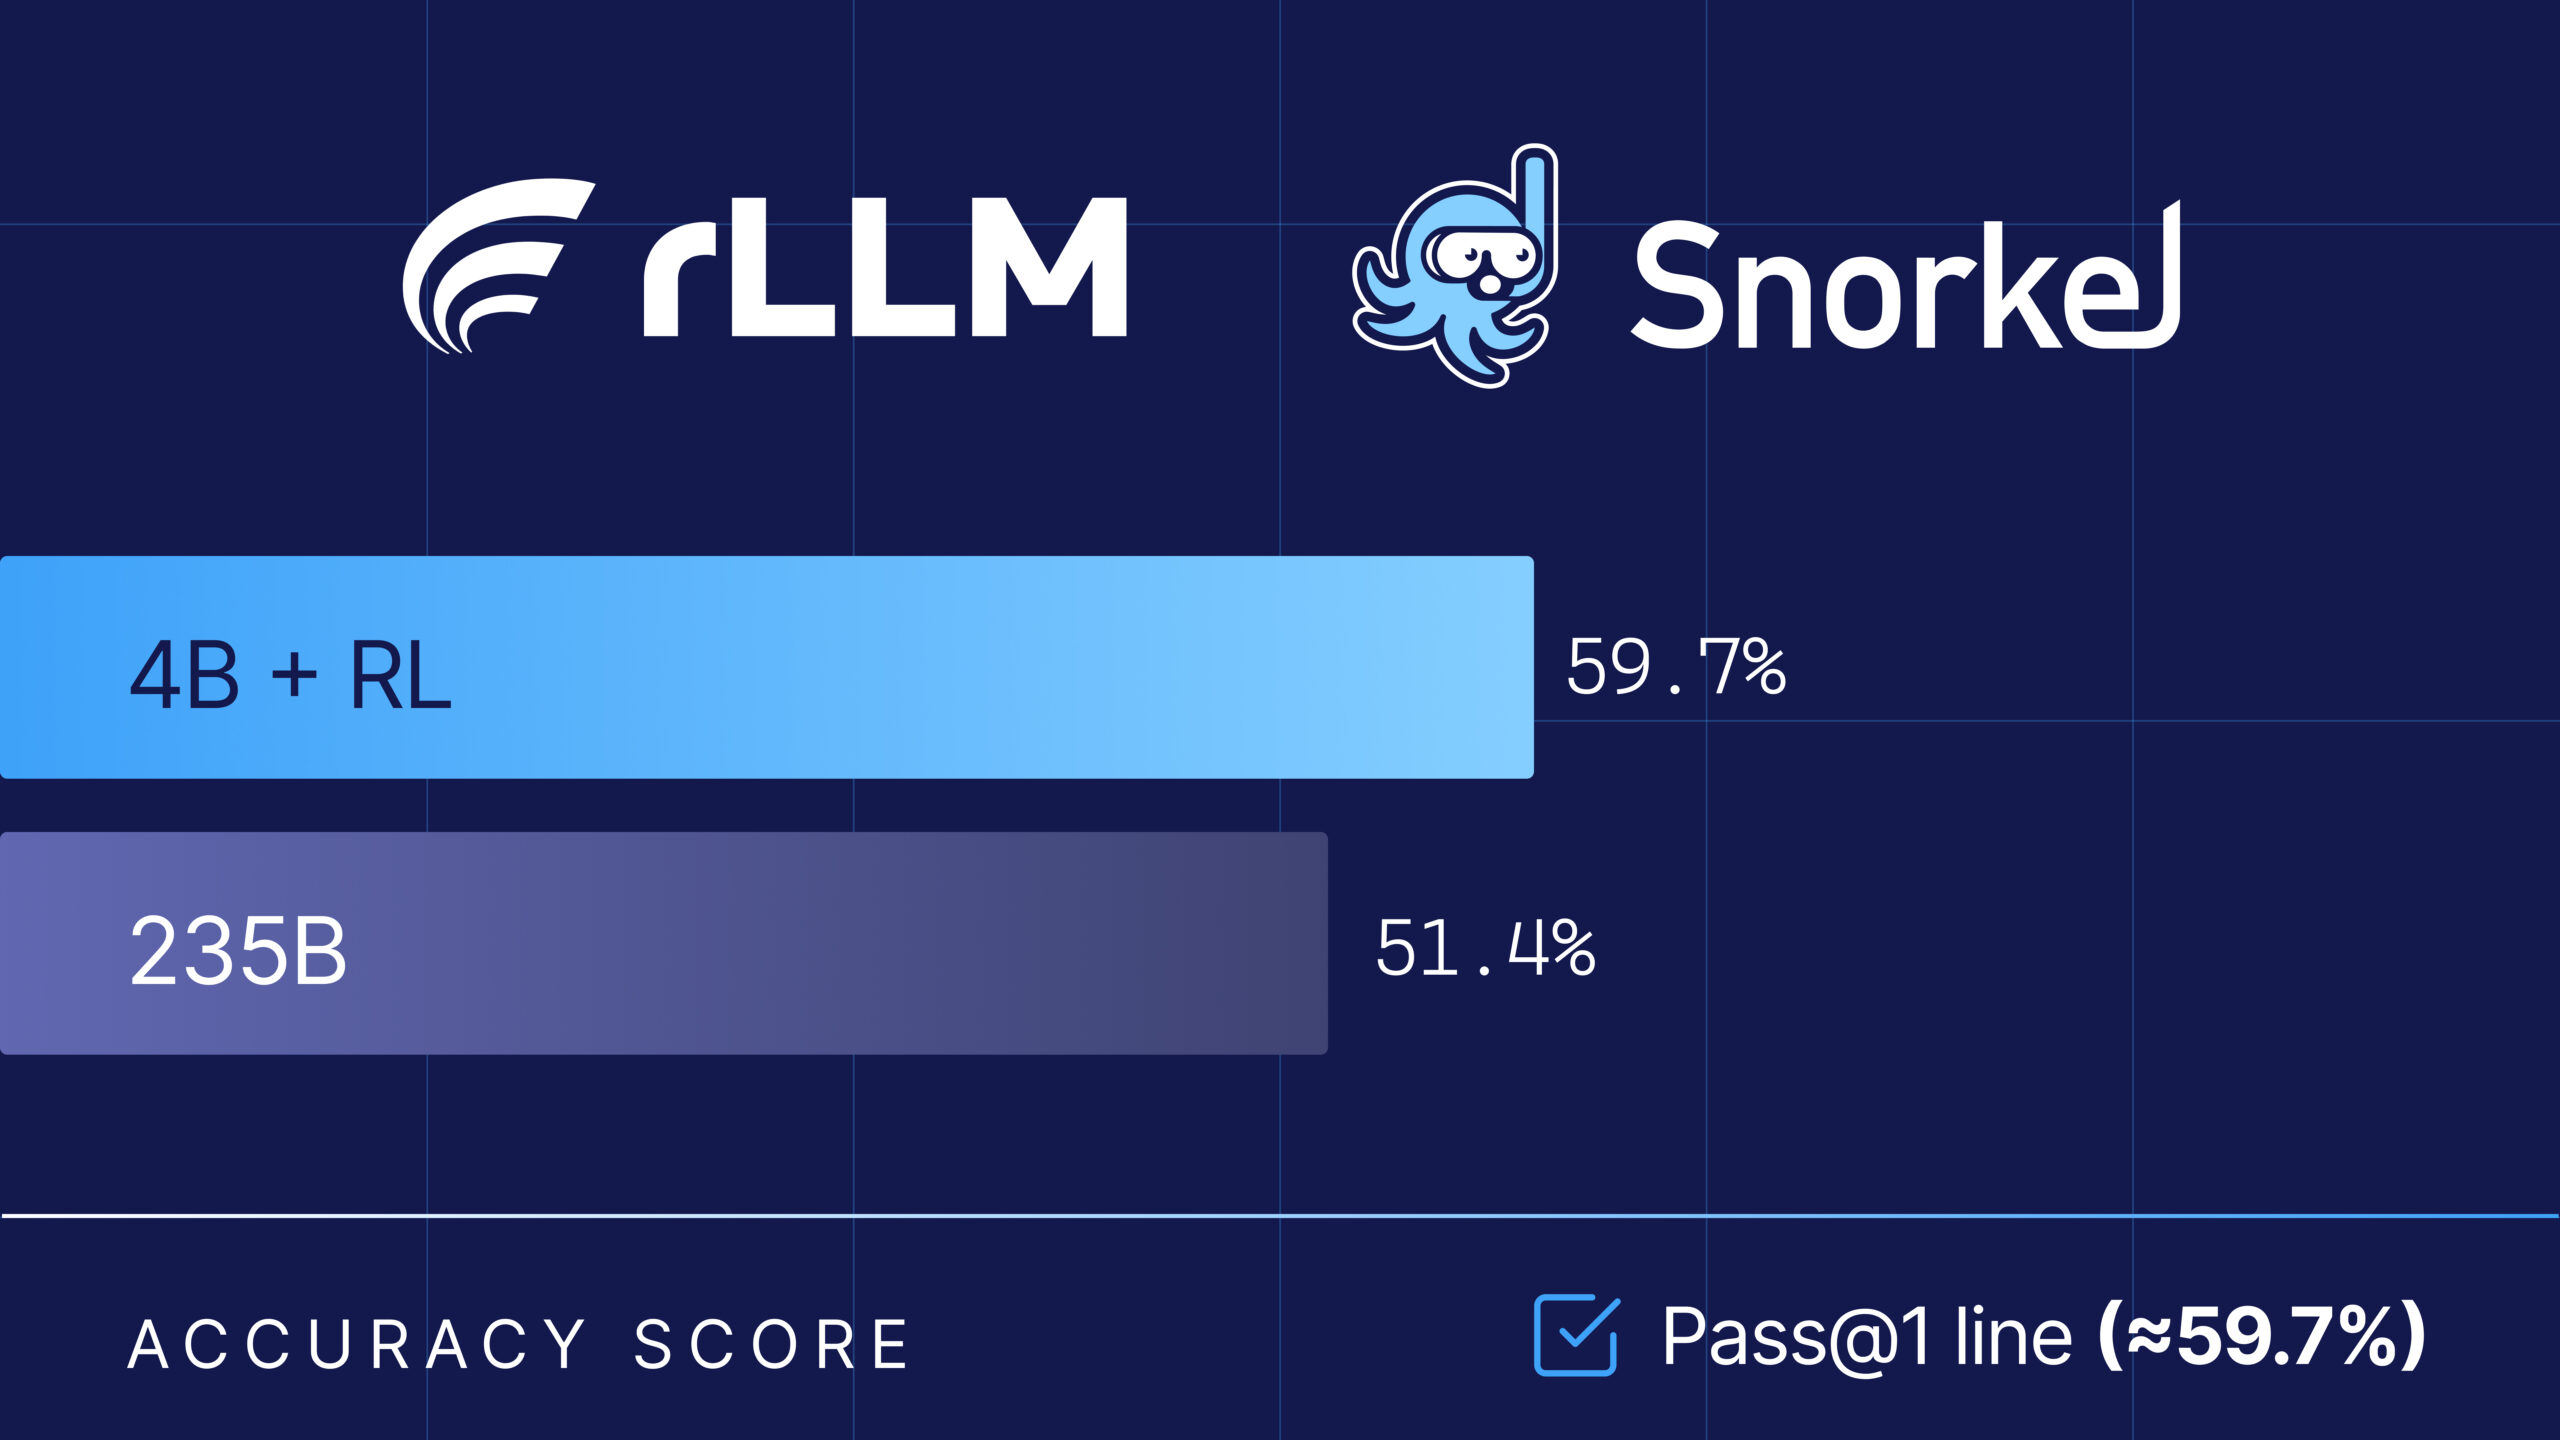
How Tool Discipline Let a 4B Model Outsmart a 235B Giant on Financial Tasks
The Snorkel research team collaborated with the rLLM team at UC Berkeley on the Agentica project, using their open-source rLLM framework to fine-tune Qwen3-4B-Instruct-2507, delivering a model that beats Qwen3-235B-A22B on Snorkel AI’s expert-curated financial benchmarks – at 1/60th the size. A full breakdown of the results are published in the rLLM blog here. The key insight? Just focus on
February 17, 2026
•
Chris Glaze
Image
Closing the Evaluation Gap in Agentic AI
Announcing a $3M commitment to launch Open Benchmarks Grants Today, AI is marked by a growing asymmetry: the excitement around agentic AI is real—backed by quantitative progress on model cards and genuine leaps forward, especially in coding. But ask individuals or enterprises where they feel ready to deploy agentic automation in high-stakes, domain-specific settings outside of coding… and you will
February 11, 2026
•
Vincent Sunn Chen
Image
Part V: Future direction and emerging trends
Explores how rubrics support agentic, multi-turn, tool-using, multimodal, and code-generating AI systems, and how they evolve with AI feedback and ensemble evaluation.
December 5, 2025
•
Justin Bauer
Image
Chat with the Terminal-Bench team
Snorkel Chief Scientist Fred Sala and Kobie Crawford chat with the Terminal-Bench team to unpack the design behind Terminal-Bench 2.0 and the new Harbor framework.
November 19, 2025
•
Fred Sala
,
Kobie Crawford
Image
Intelligence Per Watt: A New Metric for AI’s Future
Snorkel AI contributes specialized datasets to Hazy Research’s “Intelligence-per-Watt” study, advancing how efficiently AI turns energy into intelligence.
November 12, 2025
•
Kobie Crawford
Image
Snorkeling in RL environments
We unpack what makes a high-quality RL environment for LLMs and show how we build realistic, enterprise-grade environments at Snorkel AI.
November 4, 2025
•
Armin Parchami
Image
Introducing SnorkelSpatial
A procedurally generated and programmatically verified benchmark for evaluating spatial reasoning capabilities in LLMs Large language models (LLMs) are showing remarkable results on solving complex reasoning problems across domains—from mathematical proofs and logical puzzles to graduate-level science and engineering questions. On the other hand, their spatial reasoning capabilities are less understood, even though such reasoning underlies many everyday tasks. We
October 24, 2025
•
Harit Vishwakarma
Image
Scaling Trust: Rubrics in Snorkel’s Quality Process
Snorkel’s “Trusted Scale” philosophy Welcome to Part 4 of Snorkel AI’s rubric series. In previous posts, we explored how rubrics enable structured evaluation (Part 1), the spectrum of rubric types and use cases (Part 2), and the science behind designing and validating them (Part 3). In this latest installment, we pull back the curtain on how Snorkel puts these principles
October 16, 2025
•
Derek Pham
Image
Evaluating Multi-Agent Systems in Enterprise Tool Use
In recent months, there has been increasing interest in the area of multi-agent systems and how they can be used to solve more complex tasks than a single agent could accomplish on its own. The topic is particularly interesting and raises several questions and ideas to consider: Anthropic’s blog post about how they architected a multi-agent deep research system is
October 9, 2025
•
Bhavishya Pohani
Image
Evaluating Coding Agent Capabilities with Terminal-Bench: Snorkel’s Role in Building the Next Generation Benchmark
Terminal-Bench, developed through a collaboration between Stanford University and Laude Institute, has quickly become the gold standard benchmark for evaluating AI agent capabilities in a command line environment. This comprehensive evaluation framework measures how effectively AI agents can perform complex, real-world tasks within terminal environments. At Snorkel AI, we’re excited to share that we’re one of the top collaborators contributing
September 30, 2025
•
Tom Walshe
,
Kobie Crawford
,
Jeong Shin